The short answer: if you can run a service, start with Langfuse or Arize Phoenix. If you build on LangGraph, LangSmith is the lowest-friction choice. If your company already pays for Datadog, use Datadog. If your biggest fear is a release that quietly makes the agent worse, look hard at Braintrust. Don’t pick Helicone for new work. And whatever you choose, instrument with OpenTelemetry, because at least seven tools in this space were acquired or shut down between May 2025 and May 2026.
That last point is why this guide exists. Most “best tools” pages are written by a vendor that ranks itself first, and many were out of date within months. So I built this one differently, and I’ll be upfront about where it’s strong and where it isn’t.
How this guide was built, and what it can’t tell you
I did not run these tools myself. What I did instead:
- Checked prices, licenses, and product status against vendor pages and primary announcements (Cisco, ClickHouse, OpenTelemetry, each vendor’s pricing page).
- Found the one independent hands-on overhead benchmark I could locate and reported its limits.
- Treated every customer story as marketing unless an independent party ran the numbers, and labeled it.
- Flagged every place where popular rankings contradict the primary sources (Section 6).
- Gave you a 2-hour test protocol (Section 12), because the only way to learn how a tool behaves on your agent is to measure it.
I use four evidence labels in this guide:
| Label | Meaning |
|---|---|
| Primary | The vendor’s or acquirer’s own page or announcement |
| Independent test | A third party ran a documented measurement |
| Vendor-published | A customer story or claim published by the vendor |
| Secondary | A third-party page quoting a vendor, so verify before you buy |
Prices were checked in late October and early November 2026, and vendors change plans often. Confirm on the pricing page before signing anything.
Quick picks
| If you are… | Start with | The catch |
|---|---|---|
| A startup that wants traces today, cheaply | Langfuse (Hobby or self-hosted) or Phoenix | You’ll eventually run it or pay for it |
| Building on LangChain or LangGraph | LangSmith | Per-seat pricing, closed source |
| Required to keep data in your own environment | Self-hosted Langfuse, Phoenix, Opik or Laminar | Someone has to operate it |
| Already standardized on Datadog | Datadog | Cost per span at volume, 15-day default retention |
| Mostly worried about regressions between releases | Braintrust | $249 floor, closed source |
| Wanting a cheap hosted OpenTelemetry-first tier | Arize AX | Confirm overage rates yourself |
| Currently on Helicone | Plan a move | Maintenance mode since March 2026 |
| Using Galileo, Traceloop or Humanloop | Read Section 3 now | New owners, changed pricing, or shut down |
1. What agent observability actually has to do
Logging a single model call is easy: prompt in, answer out. An agent is harder. The same input can lead to different reasoning, different tool choices, and a different outcome on the next run. A useful trace has to capture the whole tree: every model call, every tool call with its arguments, intermediate decisions, token usage, latency, and, ideally, a quality score.
Vendors blur three separate jobs together:
| Job | Question it answers | Typical features |
|---|---|---|
| Tracing | What did the agent actually do? | Nested spans, tool arguments, replay |
| Evaluation | Was it any good? | LLM-as-judge, datasets, regression tests |
| Operations | Is it getting slower, costlier or riskier? | Cost per run, alerts, retention, PII controls |
Tools that began as tracers (Langfuse, Phoenix) are strongest on the first. Tools that began as evaluation platforms (Braintrust) are strongest on the second. APM vendors (Datadog) are strongest on the third, especially when agents run next to ordinary services. Knowing which job you’re buying for saves more money than any price comparison.
2. A scorecard of facts you can verify
I avoided made-up 1-to-10 scores. This table only shows things a vendor page, license file or announcement can confirm. “Partial” means available on higher or enterprise tiers only. “Not stated” means I couldn’t find it on the pages I read, which is not proof the feature is missing.
| Tool | Permissive open-source license | Self-host | States OTLP/OpenTelemetry ingest | Public self-serve pricing | Independent overhead data | Ownership unchanged in 2026 |
|---|---|---|---|---|---|---|
| Langfuse | Yes (MIT core) | Yes, free | Yes | Yes | Yes | No (ClickHouse) |
| Arize Phoenix / AX | No (Elastic License 2.0) | Yes, free | Yes | Yes | No | Yes |
| LangSmith | No | Partial (Enterprise) | Yes | Yes | Yes | Yes |
| Braintrust | No | Partial (Enterprise) | Yes | Yes | No | Yes |
| Datadog | No | No | Yes | Yes | No | Yes |
| Opik (Comet) | Yes (Apache 2.0) | Yes | Yes | Not verified by me | No | Yes |
| Laminar | Yes (Apache 2.0) | Yes | Yes | Yes | Yes | Yes |
Sources: Langfuse and ClickHouse, Arize’s license page, and the vendor-page summary in Developers Digest’s portability table (secondary, built from vendor pages as of 18 October 2026).
What the table says plainly: permissive licensing and self-hosting concentrate in Langfuse, Opik and Laminar, and every serious option now accepts OpenTelemetry. That last row of checks is why portability is realistic this year in a way it wasn’t in 2024.
3. The 2026 ownership map
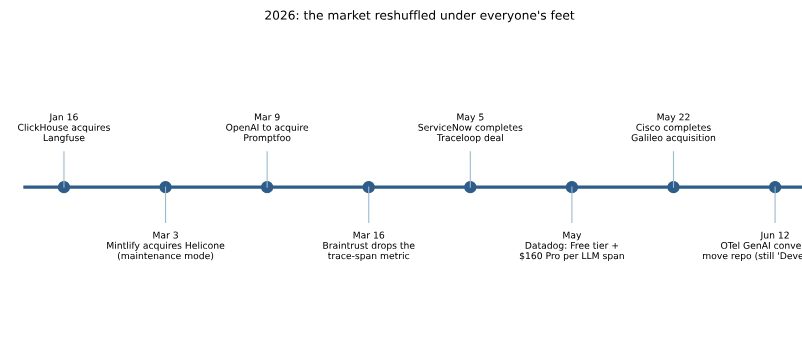
Timeline of 2026 acquisitions and pricing changes in the agent observability market Timeline of the 2026 acquisitions and pricing changes. Dates are explained in the table below.
| Tool | Now part of | Date | What it means in practice |
|---|---|---|---|
| Langfuse | ClickHouse | 16 Jan 2026 | Core stays MIT; Cloud keeps running standalone, per ClickHouse. Langfuse’s own post says the whole team joined |
| Helicone | Mintlify | 3 Mar 2026 | Maintenance mode: security fixes and new model support, but no new features |
| Promptfoo | OpenAI | Announced 9 Mar 2026 | Stays MIT and open source per its README, with enterprise features going into OpenAI’s platform |
| Traceloop | ServiceNow | Completed by 5 May 2026 | OpenLLMetry remains Apache 2.0 |
| Galileo | Cisco (Splunk) | Completed 22 May 2026 | Cisco confirmed the close; pricing now lives on a Splunk page |
| W&B Weave | CoreWeave | Completed 5 May 2025 | Priced and documented under CoreWeave |
| Humanloop | Team joined Anthropic | Platform sunset 8 Sep 2025 | The product is gone; teams had a deadline to export |
(Dates for Promptfoo, Traceloop, W&B and Humanloop come from the Developers Digest consolidation tracker, which links each acquirer’s own announcement. Treat it as secondary and check the links if the detail matters to you.)
Two other 2026 changes affect your budget directly. Braintrust removed its trace-span metric in March. Datadog moved to a free tier plus $160 Pro priced per LLM span.
The lesson isn’t “avoid acquired tools.” Langfuse’s public commitments are encouraging. The lesson is that a tool’s roadmap follows its owner, and a ranking published in spring may already be wrong. The part of your stack that should belong to no vendor is your instrumentation and your test suite.
4. The only independent overhead test I found
Observability isn’t free: it adds work to your agent’s execution path. AIMultiple, a research firm, measured it by running 100 identical queries through a five-stage LangChain travel-planning agent, once without instrumentation and once with each tool, on the same server with temperature set to 0.
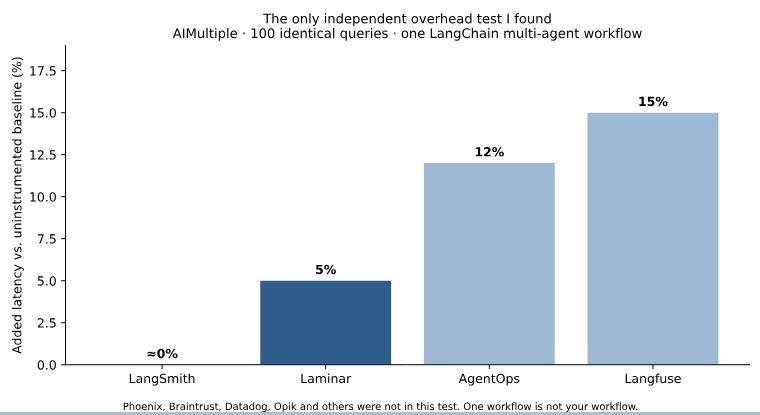
Bar chart of added latency: LangSmith about 0%, Laminar 5%, AgentOps 12%, Langfuse 15%. Added latency per tool in AIMultiple’s October 2026 benchmark: one LangChain workflow, 100 queries per tool.
Read the limits before quoting these numbers:
- It’s one workflow, built on LangChain. A tool with tight LangChain integration is expected to look good in it, and AIMultiple itself says integration tightness affected results.
- Only four tools were measured. Phoenix, Braintrust, Datadog, and Opik were not.
- It’s a single run of 100 queries per tool, with no confidence intervals shown.
- AIMultiple discloses that W&B is a subscriber to its benchmarking services; W&B was not among the four measured tools.
What I take from it: instrumentation depth matters, and “the tool with the most detail may cost the most latency” is plausible and worth testing on your own stack. It doesn’t prove Langfuse is slow in your system or that LangSmith is free in yours. That’s what Section 12 is for.
5. The tools, one by one
Langfuse: the open-source default (with one caveat)
What it is. An MIT-licensed LLM engineering platform you can self-host at production scale on ClickHouse, or run as Langfuse Cloud. It accepts OpenTelemetry traces.
Pricing (Langfuse pricing page, summarized by ZenML; secondary): Hobby is free with 50k units and 2 users. Core is $29 with 100k units, then $8 per extra 100k. Pro is $199 with 3-year retention. Enterprise is $2,499. SSO and project-level roles on Pro need a $300 Teams add-on. A “unit” is a trace, an observation, or a score, so a deep agent run burns many units.
Who uses it? Langfuse’s own customer pages feature Ramp, SumUp, Canva, Magic Patterns and Slite (Section 7). ClickHouse’s announcement names Intuit, Twilio, 7-Eleven and Merck as enterprise users.
The caveat. It showed the highest overhead (15%) in the one independent test above. That’s a single workflow, but it’s a reason to measure before committing. Ownership is also new, and public commitments aren’t guarantees.
Arize Phoenix and Arize AX: OpenTelemetry-first
What it is. Phoenix is open source under the Elastic License 2.0, not Apache 2.0 as at least one comparison states. Arize’s license page says self-hosting is free with no feature gates. ELv2 restricts, among other things, offering the software to others as a managed service, so have legal read it if that’s your business. Phoenix is built on OpenTelemetry. AX is the hosted product.
Pricing (Arize pricing): AX Free gives 25k spans a month, 1 GB, and 15-day retention. AX Pro is $50 a month for 50k spans, 10 GB, and 30 days, with no per-seat fee. Overage rates of roughly $10 per million spans and $3 per GB appear in third-party summaries but not on the page I read, so verify them. At least one third-party site lists a much higher per-span overage, which looks like an error.
Verdict. The cheapest hosted entry among the commercial options, and the strongest pick when OpenTelemetry portability outranks polish.
LangSmith: best fit for LangChain and LangGraph
What it is. The hosted observability and evaluation product from the LangChain team. Tracing, datasets, online evals, annotation queues, and managed agent deployment sit in one product.
Pricing (LangSmith pricing): Developer is free for one seat with 5k base traces a month. Plus is $39 per seat with 10k base traces. Enterprise is custom and is where self-hosted or hybrid deployment lives. Overage is described inconsistently: the older docs page says $0.005 per trace, while newer third-party breakdowns say $2.50 per 1,000 base traces and $5.00 for 400-day retention, plus separate compute and storage units. Budget from the live calculator.
Evidence. It posted about 0% overhead in the independent test (LangChain workflow, as noted). Its case studies are vendor-published (Section 7).
Verdict. If your agents live in LangGraph, the integration is a real advantage. If they don’t, you’re paying per seat for depth you won’t use.
Braintrust: evaluation first
What it is. An evaluation-centred platform with tracing and monitoring around it. Accepts OpenTelemetry traces and logs; self-hosting is an Enterprise option.
Pricing (billing docs, ZenML breakdown): Starter is $0 with $10 in credits, 1 GB processed data, 10k scores, and 14-day retention. Pro is $249 a month with 5 GB, 50k scores, and 30-day retention. Unlimited users on every tier. Overage is metered on processed data (about $3 to $4 per GB) and scores, not spans (Flexprice).
Verdict. Worth it if “did this change make the agent worse?” is your main question. Less compelling if you mainly need cheap tracing. There’s no mid-priced tier between free and $249.
Datadog: the answer for teams already on Datadog
What it is. LLM and agent monitoring inside the Datadog platform, which Datadog’s docs now present under the “Agent Observability” name. It supports OpenTelemetry GenAI conventions, per the vendor-page summary.
Pricing (Datadog product page): Free includes up to 40k LLM spans a month. Pro starts at $160 a month with 100k spans included. Third-party summaries give $3.50 per extra 10k spans on an annual contract, with higher month-to-month and on-demand rates, and retention add-ons that rose sharply in autumn. The old “$8 per 10,000 requests” still circulates on older pages and is no longer the live model.
Verdict. The logic is correlation: agent traces next to the database and API traces they depend on. If you’re not a Datadog customer, there’s little reason to start here.
Opik (Comet): the open-source challenger
Apache 2.0, native OpenTelemetry support, self-hostable without a commercial license, per the vendor-page summary. Comet is also the vendor of Opik, so treat its own rankings as marketing. A third-party comparison lists a free cloud tier of 25k spans and a $19 Pro plan, which I couldn’t confirm on Comet’s page. Worth a pilot if you want an open-source option that isn’t Langfuse or Phoenix.
Laminar: lightweight and open source
Apache 2.0, native OTLP ingest, Docker Compose or Helm self-hosting, and pricing by gigabytes stored with no seat fees, according to Laminar’s own comparison page (vendor-published). It posted 5% overhead in the independent test. A younger project, so check its community and release cadence before betting a platform on it.
Also worth knowing
| Tool | What to know | Source quality |
|---|---|---|
| Galileo | Now inside Cisco’s Splunk. The Splunk page lists agent observability from about $100 a month per 1.2M spans, billed annually | Secondary |
| Traceloop / OpenTelemetry | ServiceNow-owned; the OpenLLMetry instrumentation library is Apache 2.0 and OpenTelemetry-based, so your instrumentation stays portable | Secondary |
| W&B Weave | CoreWeave-owned; Apache 2.0 repository; accepts OTLP | Secondary |
| Confident AI (DeepEval) | Hosted layer on the open-source DeepEval framework. Its pricing page shows per-user pricing from $19.99, while its own comparison page lists a flat $200 Starter plan. Its two pages disagree, so ask for a quote | Primary, conflicting |
| AgentOps | MIT, self-hostable, 12% overhead in the independent test | Independent test + secondary |
| MLflow | Apache 2.0 open-source platform, strongest if you’re already on Databricks or MLflow | Secondary |
| Portkey | A gateway rather than a pure tracer. Arize’s blog lists a free developer tier and a $49 Production plan with an open-source self-hosted gateway | Vendor-published (competitor) |
| Maxim AI | Simulation-first; Arize’s blog lists $29 per seat per month for its Professional tier | Vendor-published (competitor) |
| Helicone | Maintenance mode since 3 March 2026. Its license is reported as Apache 2.0 in one tracker and MIT in another, so check the repository | Primary + conflicting |
6. Where the popular rankings contradict the primary sources
This is the part you can’t get from a vendor’s “best of” list. I found each of these by comparing published rankings with primary pages.
| What you’ll read | What the primary source says | Why it matters |
|---|---|---|
| Phoenix is Apache 2.0 | Arize’s docs say Elastic License 2.0 | Different obligations if you build a product on it |
| Datadog is “contact sales” or “$8 per 10k requests” | Live page: Free tier + $160 Pro, priced per LLM span | Old figures can wreck a budget |
| Braintrust gives 1M free spans, or charges a percentage fee | Span metric removed in March 2026; billing is on processed data and scores | A span-based “free” estimate is wrong |
| Helicone is the quick-setup default | Maintenance mode since 3 March 2026 | New projects inherit a tool with no roadmap |
| OTel GenAI conventions are “stable” | Spec and independent explainers: every gen_ai.* attribute is still Development | Attribute names can change |
| LangSmith costs X per trace | Sources disagree: $0.005 vs $2.50 to $5.00 per 1k | Use the live calculator |
| Confident AI is $200 flat, or per-user | Its pricing page and comparison page differ | Get a written quote |
| Helicone is MIT licensed | Another tracker says Apache 2.0 | Check the repository license file |
| One “case study” of a Langfuse rollout | The customer is anonymous, and the author is an agency | I excluded it as unverifiable |
7. What real production cases show
Here is the uncomfortable truth: independent, named, quantified case studies for observability tools barely exist. Almost everything public is published by the vendor, so I’ve included stories from both major camps and labeled them.
| Case | Reported result | Published by | Trust level |
|---|---|---|---|
| Klarna (LangSmith + LangGraph) | Average resolution time cut 80% over nine months | LangChain, Feb 2025 | Vendor-published; the 80% belongs to the whole assistant, not tracing alone |
| Podium (LangSmith) | 90% less engineering intervention; F1 98.6% | LangChain | Vendor-published, no method shown |
| Rakuten (LangSmith) | Accuracy moved from 70% to 80% using pairwise evaluations | LangChain | Vendor-published quote |
| monday.com (LangSmith) | Evaluation feedback loops roughly 9x faster | LangChain customers | Vendor-published headline |
| Ramp (self-hosted Langfuse) | Agent sessions 30% faster, 15% fewer tool calls, using trace-driven fixes | Langfuse, Sep 2026 | Vendor-published |
| SumUp (Langfuse) | 50% support deflection and 30% lower outsourcing costs for a 35+ market rollout | Case study page | Vendor-published |
| Magic Patterns (Langfuse) | Support resolution kept under 8 minutes by opening the trace the moment a customer pings | Langfuse | Vendor-published quote |
| Slite (Langfuse) | Moved from quarterly experiments to confident weekly changes using a dataset and eval pipeline | Langfuse | Vendor-published |
| CallSphere (LangSmith) | 412 voice and 287 chat regression rows, each from a real complaint | Founder’s post | Self-reported by a small vendor |
What they have in common. Across both camps, the value didn’t come from a prettier dashboard. It came from a loop: trace the failure, turn it into a test case, run the test before shipping. Klarna describes step-by-step tracing plus tested use cases and evaluation-driven prompt iteration. Slite swapped a spreadsheet for a dataset-and-eval pipeline. Ramp describes turning traces into merged fixes. That is my reading of the sources, not something any of them states as a rule, but it’s consistent enough to act on: pick the tool whose traces flow most easily into your test set.
What the community says. On the Hacker News thread about ClickHouse buying Langfuse, reactions split three ways, as summarized by Developers Digest: loyal users hoped the deal makes Langfuse better, one commenter said they’d move away over data-access laws, and another said they’d already moved to a general error-tracking tool like Sentry and asked what a specialist tracer adds. Anecdotes, not evidence, but the “do I need a specialist at all?” question is worth asking before you buy.
8. What it costs: one workload, six bills
Pricing units differ so much that “starts at $29” and “starts at $249” can’t be compared. So I ran one hypothetical workload through each published price list.
My assumptions: 50,000 agent runs a month; each run is one trace with 10 spans; five people on the team; about 20 KB per span; scores and evaluation runs excluded; list prices, no discounts.
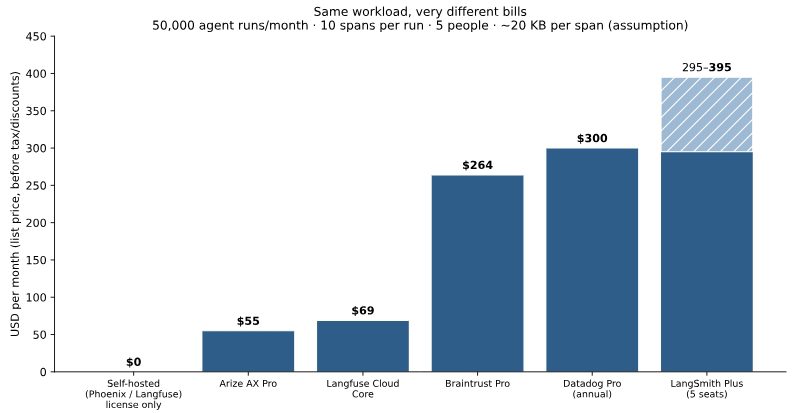
Illustrative monthly cost for the same workload across platforms. Illustrative monthly cost for one hypothetical workload. The hatched area marks LangSmith’s range.
| Platform | How the workload is counted | Estimated monthly cost |
|---|---|---|
| Phoenix or Langfuse, self-hosted | Free software; your infrastructure and time | $0 license |
| Arize AX Pro | 500k spans, 10 GB; overage only on spans (about $4.50 at the quoted rate) | ≈ $55 |
| Langfuse Cloud Core | 550k units (50k traces + 500k observations): $29 + five $8 blocks | ≈ $69 |
| Braintrust Pro | 10 GB processed vs 5 GB included, extra $3/GB | ≈ $264 |
| Datadog Pro (annual) | 500k LLM spans: $160 + 40 blocks × $3.50 (assumes every span counts) | ≈ $300 |
| LangSmith Plus | 5 seats × $39 + 40k extra traces at $2.50 to $5 per 1k | ≈ $295 to $395 |
How to read this:
- It’s an illustration, not a quote. Change the span count or payload size and the order shifts. A team with few traces and many spans per trace looks much better on LangSmith; a team with huge payloads looks worse on Braintrust.
- The same workload is counted differently everywhere: 50k traces, 550k units, 500k spans, 10 GB. That’s why price pages are hard to compare, and why you should always convert your own workload into each vendor’s unit.
- “Free self-hosted” isn’t free. Someone runs the database, upgrades, and backups.
- Spend controls differ. LangSmith lets you set a monthly trace limit. Langfuse’s spend alerts don’t cap the bill, per ZenML’s review. Set an alert before production, whichever you choose.
9. Should you build on OpenTelemetry?
Yes for export, with caution about relying on attribute names.
OpenTelemetry’s agent span specification defines spans for creating and invoking agents and executing tools. It’s still labeled “Status: Development”, and as of mid-2026, no gen_ai.* attribute has reached Stable. In June, the conventions moved to their own repository so they can change faster.
In practice:
- Instrument once with OpenTelemetry, and moving between backends becomes a configuration change rather than a rewrite.
- Pin your instrumentation library versions. Names and structure can still change.
- Don’t tell your team the standard is finished. It isn’t.
A minimal way to keep your exit open is to put an OpenTelemetry Collector in front of your vendor. It lets you send the same traces to two destinations and to a file you control. Endpoints and auth headers differ by vendor, so take them from each vendor’s OTLP docs. The file exporter ships in the Collector’s contrib distribution.
yaml
receivers:
  otlp:
    protocols:
      grpc:
      http:
processors:
  batch:
exporters:
  otlphttp/primary:
    endpoint: ${env:PRIMARY_OTLP_ENDPOINT}
    headers:
      Authorization: ${env:PRIMARY_OTLP_AUTH}
  otlphttp/secondary:
    endpoint: ${env:SECONDARY_OTLP_ENDPOINT}
    headers:
      Authorization: ${env:SECONDARY_OTLP_AUTH}
  file/archive:
    path: /var/otel/traces.jsonl
service:
  pipelines:
    traces:
      receivers: [otlp]
      processors: [batch]
      exporters: [otlphttp/primary, otlphttp/secondary, file/archive]
Humanloop is why this matters. Its platform was sunset with a published deadline, and teams whose prompts and eval history lived only inside it had to export in a hurry.
10. Pick by situation, and my ranking
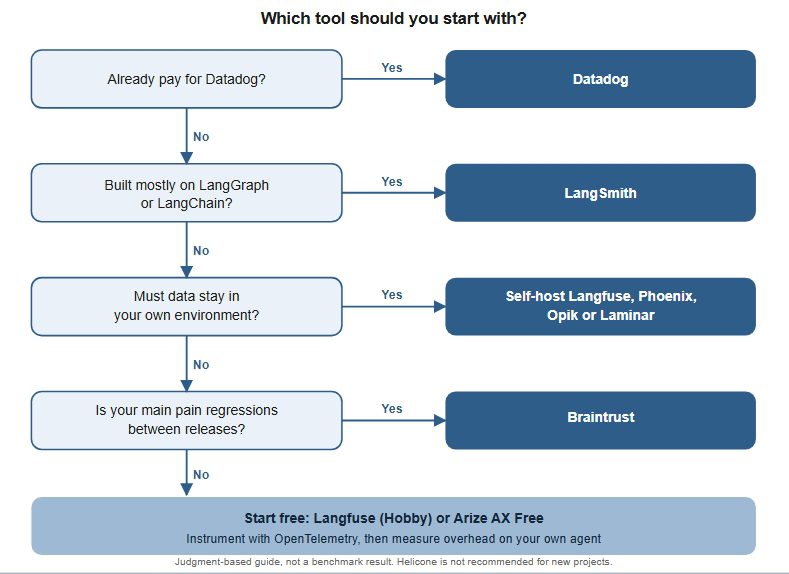
Decision flow: Datadog if you already pay for it, LangSmith for LangGraph, self-hosted open source if data must stay in your environment, Braintrust if regressions are the pain, otherwise start free with Langfuse or Arize AX. Decision flow: a judgment-based guide to where to start, not a benchmark result.
| Situation | Pick | Why |
|---|---|---|
| Starting from zero, small team | Langfuse or Phoenix | Free to start, open, portable |
| Heavy LangGraph use | LangSmith | Native integration and managed deployment |
| Data must stay in your environment | Self-hosted Langfuse, Phoenix, Opik or Laminar | You control storage |
| Datadog shop | Datadog | One place for agent and infrastructure traces |
| Regression testing is the main pain | Braintrust | Built around evaluation |
| Wanting a $50 hosted OpenTelemetry-first tier | Arize AX | Cheapest paid entry |
| Already on Helicone | Migrate on your schedule | Maintenance mode |
My default ranking for a typical team starting today:
- Langfuse for openness, price transparency, and an easy exit, with the overhead caveat above
- Arize Phoenix / AX for OpenTelemetry-first design and the cheapest hosted tier
- LangSmith for LangGraph users (move it to #1 if that’s you)
- Braintrust for evaluation-driven teams
- Datadog (move it to #1 if you already run Datadog)
- Opik and Laminar, tied, as open-source challengers worth a pilot
- Helicone, not for new projects
This is my judgment, weighted toward openness, price transparency, portability, and ownership risk. It is not a benchmark result, and the order flips with your stack.
11. Your first 30 days
- Week 1: instrument before you optimize. Trace one agent end to end, including tool boundaries. If a tool call is a black box, the trace is half a trace.
- Week 1: set limits. Turn on spend alerts or usage caps, and check default retention (Datadog Free keeps 15 days; Langfuse Hobby 30).
- Week 2: decide what you store. Decide which prompts and tool outputs may be recorded, and plan masking or redaction for sensitive fields.
- Week 2 to 3: build the loop. Turn every real failure into a saved test case and run an evaluation on a sample of production traffic.
- Week 3: add a quality score you trust. An LLM-as-judge score is a signal, not a verdict. Have a person review a sample.
- Week 4: review the bill and the exit. Compare your estimate with the real invoice, and confirm you could export your traces if you had to switch.
12. Run your own 2-hour test
The only way to get a real “tested” ranking is to measure your agent. This protocol copies the logic of the independent benchmark above and adds the checks that matter most to your team.
Setup: pick one real agent workflow. Fix the model, temperature 0, and a set of 100 representative queries. Run all tests on the same machine, one tool at a time.
| Measure | How | Why it matters |
|---|---|---|
| Baseline latency | Run 100 queries with no instrumentation; record p50 and p95 | The reference for overhead |
| Overhead | Re-run with each tool; compute (tool − baseline) ÷ baseline | Instrumentation depth has a cost |
| Setup time | Stopwatch from “sign up” to “first complete trace” | Hidden adoption cost |
| Trace completeness | Does a tool call and a sub-agent appear in the trace tree with arguments? | The core job |
| Export test | Re-send the same spans to a second backend using the Collector config above | Proves your exit |
| Cost | Convert your real span and payload counts into each vendor’s unit and compare with the first invoice | Beats any price page |
Record results like this:
| Tool | Overhead % | Setup minutes | Trace complete? | Export worked? | Month-1 cost |
|---|---|---|---|---|---|
If you run it and share your numbers, I’d rather you publish a “tested” section with your data than rely on mine. That is the version of this article that deserves the word “tested.”
FAQ
What is the best AI agent observability tool in 2026? There isn’t one. For most teams starting from zero, Langfuse or Arize Phoenix is a sensible default. LangSmith suits LangGraph users, Datadog suits existing Datadog customers, and Braintrust suits evaluation-driven teams.
What is the difference between LLM observability and agent observability? LLM observability logs single model calls. Agent observability follows a multi-step run: planning, tool calls, sub-agents, retries, and the outcome.
Which AI agent observability tools are free or open source? Langfuse (MIT core), Opik, Laminar, and AgentOps are permissively licensed; Phoenix is source-available under the Elastic License 2.0. Hosted free tiers exist at Langfuse (50k units), Arize AX (25k spans), Datadog (40k LLM spans), LangSmith (5k traces, one seat), and Braintrust (Starter).
Which tools were acquired in 2026? Langfuse (ClickHouse), Helicone (Mintlify), Promptfoo (OpenAI), Traceloop (ServiceNow) and Galileo (Cisco). W&B (CoreWeave) closed in 2025, and Humanloop shut down in 2025.
Is Helicone dead? No, it still runs, but it’s in maintenance mode, so it’s a poor choice for new projects.
Is Langfuse still open source after the ClickHouse acquisition? Per ClickHouse, the core stays MIT-licensed and self-hostable, and Langfuse Cloud continues as a standalone service.
Does agent observability slow my agent down? It can. In one independent test of a LangChain multi-agent workflow, measured overhead ranged from about 0% to 15% depending on the tool. Test your own workflow before committing.
Do I need OpenTelemetry? You don’t need it to start, but it reduces lock-in. Keep in mind the GenAI conventions are still in Development status.
Can I trust “best tool” lists? Trust facts you can click through to, and discount rankings written by the vendors being ranked. That includes any “#1 overall” claim.
Sources
Primary and vendor pages
- Langfuse: acquisition post, pricing, customer stories
- ClickHouse: acquisition post, Business Wire release
- Helicone: joining Mintlify
- Cisco: Galileo acquisition
- Arize: Phoenix license, pricing
- LangSmith: pricing, docs pricing, Klarna case study
- Braintrust: billing docs
- Datadog: LLM Observability
- Confident AI: pricing
- OpenTelemetry: GenAI agent spans spec
Independent and third-party (used for cross-checking)
- Benchmark: AIMultiple agent observability benchmark (updated 14 October 2026)
- Ownership tracker: Developers Digest consolidation report (18 October 2026)
- Pricing change logs: Braintrust, Datadog
- Pricing explainers: ZenML on Langfuse, ZenML on Braintrust, Flexprice on Braintrust
- OpenTelemetry status: Dash0 explainer
- Community: Hacker News thread on the Langfuse acquisition
Vendor “best of” pages reviewed (read with their authors’ interests in mind) Braintrust · Confident AI · Arize · Comet · Laminar · Respan · Augment Code
Limitations, plainly: I did not benchmark these tools myself. Several figures (Arize overage rates, Opik and Maxim pricing, Galileo’s Splunk price, some licenses) come from third-party pages quoting vendors, and they’re marked. The cost model uses my own assumptions. Customer stories are vendor-published. The ranking is judgment, not a measurement.